Model training
Build a cluster plan around model size, dataset and training window. Balance accelerator capacity with communication between nodes and reliable access to training data.
Focus: scale, interconnect, checkpoints
 1800 886 718
Cooma GPU Cloud
Train models. Fine-tune for your domain. Run inference in production. Choose GPU virtual machines, bare-metal servers or managed clusters, with flexible short-term reservations and an Australian team supporting your deployment.
Plan your GPU deploymentBuilt around the work
Each stage places different demands on compute. Start with the workload, then size the environment.
Build a cluster plan around model size, dataset and training window. Balance accelerator capacity with communication between nodes and reliable access to training data.
Focus: scale, interconnect, checkpoints
Adapt models to your domain, compare experiments and evaluate results. Match the environment to your research cycle and the capacity each run needs.
Focus: memory, experiments, project duration
Run your model stack on dedicated GPUs. Size capacity around model memory, concurrent requests, response time and the cost of serving your workload.
Focus: latency, throughput, utilisation
Looking for model API access? Explore Cooma TokenFactory
A complete compute environment
Choose how you want to run. We bring compute, networking, storage and your operating environment together around the workload.
Choose your compute
Explore NVIDIA B300, H200 and H100 capacity. We match the platform to your model, then confirm memory, node count, networking and storage.
 Blackwell Ultra
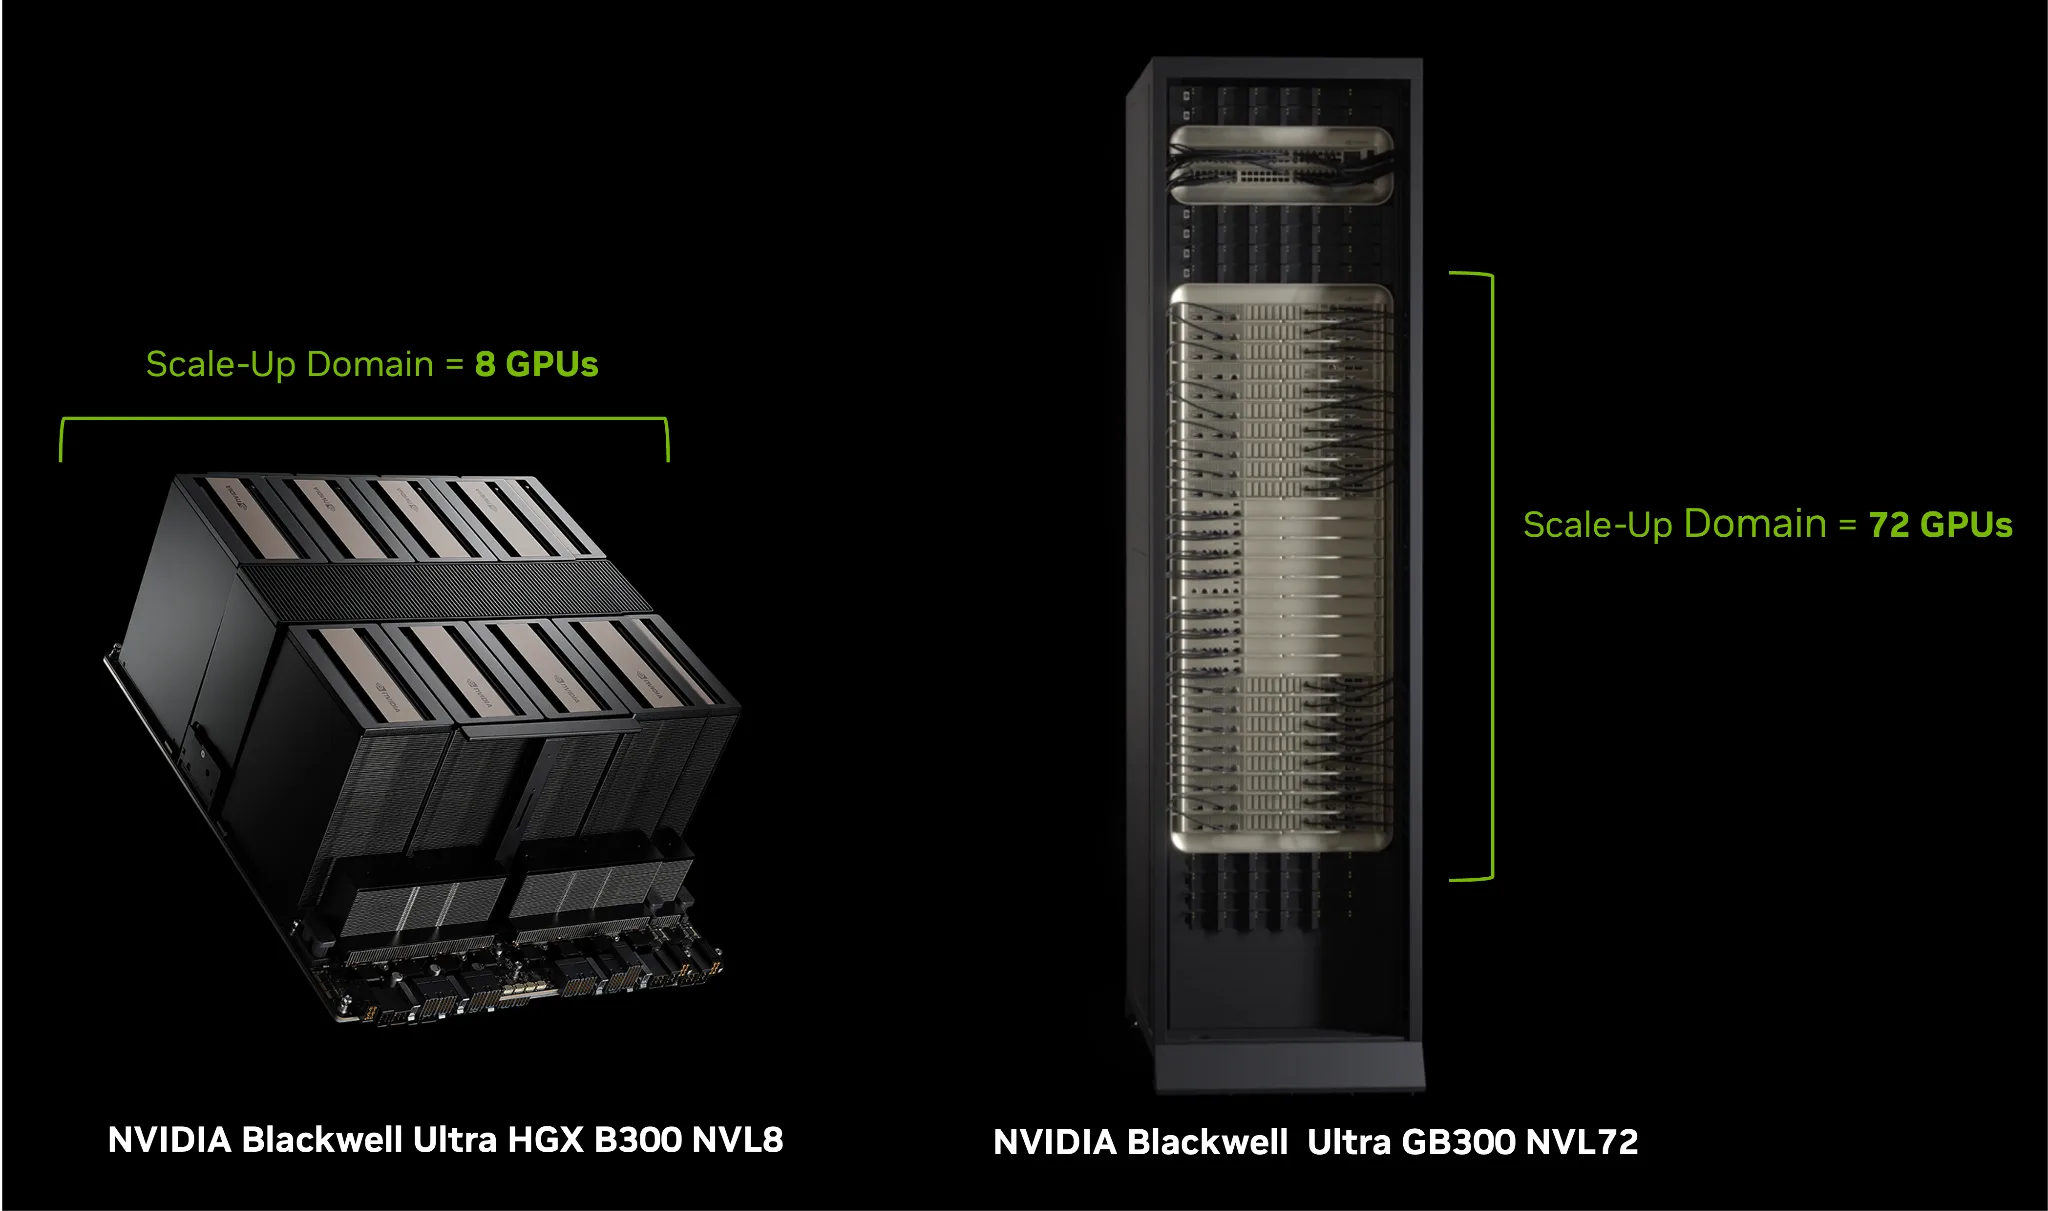
Explore Blackwell Ultra for your next training or inference deployment. Discuss model size, precision and the complete server configuration with Cooma.
Enquire about B300Hopper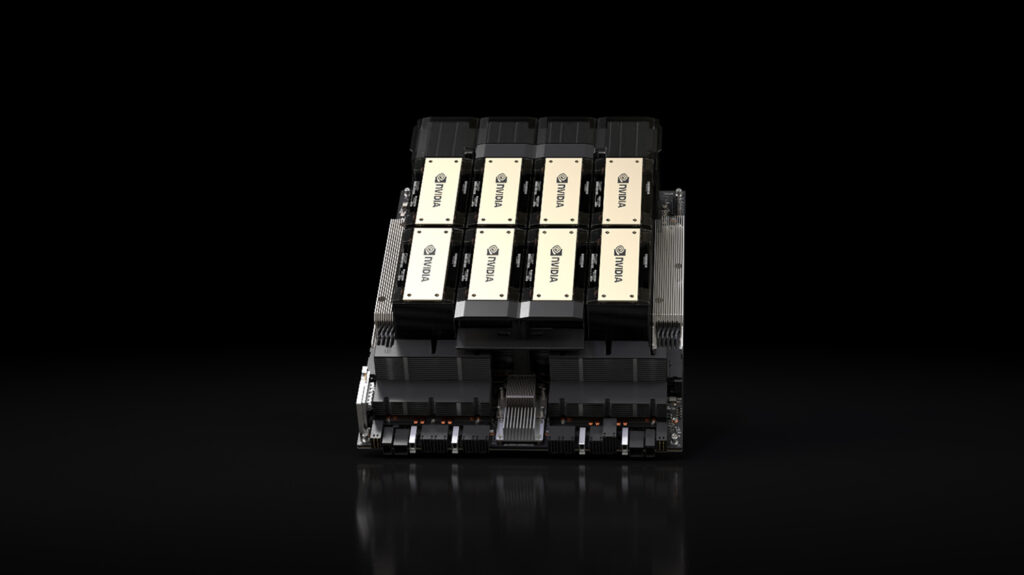
Explore H200 for workloads where model memory and data movement shape the deployment. We work through the fit for your training, fine-tuning or inference stack.
Enquire about H200Hopper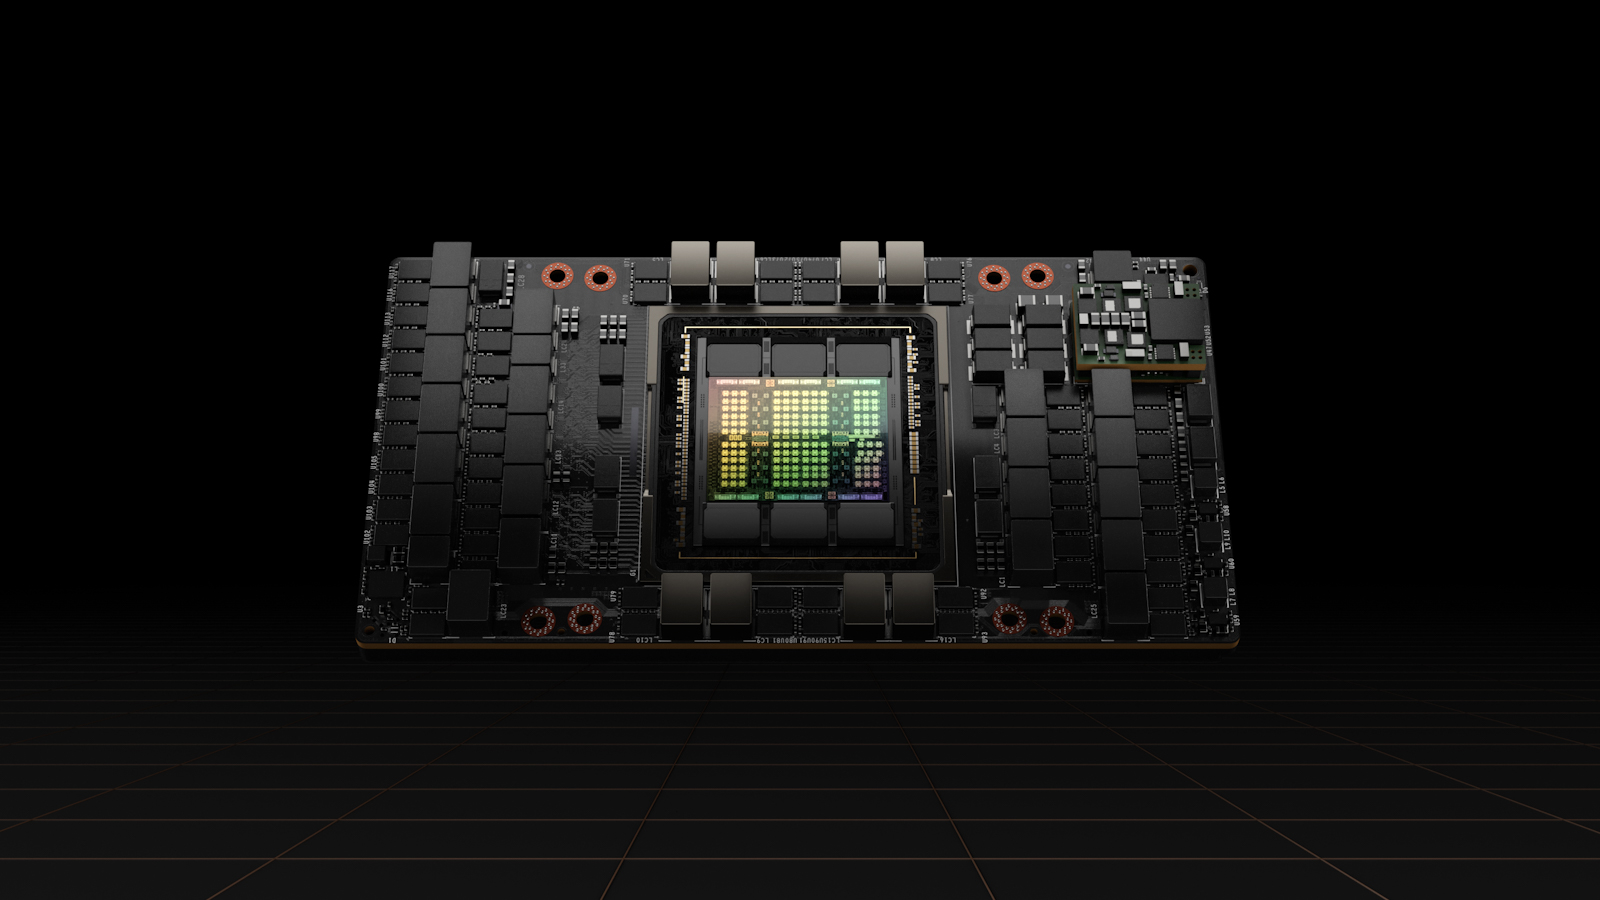
Explore H100 for training, experimentation and production inference. Define your node count, interconnect and software requirements with our team.
Enquire about H100Product imagery: NVIDIA. Exact GPU variant, server specification, location and availability are confirmed in your proposal.
Global infrastructure
An Australian point of contact, with access to global infrastructure supply. Plan your deployment across North America, Europe and Asia Pacific around data location, connectivity and delivery requirements.
Capacity is sourced through infrastructure providers. The map shows supplier regions; the facility, data boundaries and available capacity are confirmed for your deployment.
Discuss your deployment
Supplier regions · North America · Europe · Asia Pacific
Capacity & economics
Reserve GPUs for a defined project or plan for sustained production. Flexible short-term reservations let you align capacity with training runs, experiments and changing workload needs.
An example showing how GPU count and duration combine into reserved capacity.
60 GPU-days reserved
Security & control
Start with the sensitivity of your workload and your organisation’s security requirements. Confirm the controls, supporting evidence and responsibilities for the proposed deployment before proceeding.
Assess the facilities and hardware behind the capacity.
Define the boundaries around systems, users and data.
Make ownership clear across Cooma, providers and your team.
Controls and assurance vary by provider, location and service. Dedicated bare metal alone does not establish every safeguard. Any certification must be assessed against the organisation, facility and service it actually covers.
Discuss your security requirementsFrom requirement to deployment
Share your model or application, dataset, target performance, preferred region and start date. We turn that brief into compute requirements.
Review GPU and node counts, memory, network fabric, storage and orchestration. Agree how the environment will be accessed and validated.
Set the capacity window, price, deployment scope and support ownership. Define acceptance criteria and how changes or expansion will be handled.
Before we talk
Yes. Cooma offers managed Slurm for scheduled compute jobs and managed Kubernetes for containerised workloads. Configuration, access, monitoring, maintenance and support responsibilities are agreed for each deployment.
Yes. Flexible short-term reservations are available for project workloads. We confirm the GPU configuration, quantity, region, start date, duration and price in your proposal, including any extension or change conditions.
Yes. Cooma offers GPU virtual machines and dedicated bare-metal servers, including connected clusters. We match the deployment type to your workload, software stack and level of infrastructure control.
We work with global rented infrastructure capacity, including H100, H200 and B300 servers. Specific locations, quantities and deployment dates are confirmed against your requirements.
Yes. Cooma scopes GPU environments for model training, fine-tuning, research and production inference. We match GPU memory, interconnects, storage and software requirements to the workload before agreeing the deployment.
Responsibilities depend on the service agreed. Confirm ownership of physical safeguards, server and network access, operating-system patching, application security and data protection before deployment. Support, incident escalation and recovery arrangements also need an agreed owner.
We provide commercial terms for the agreed configuration and duration. Support scope, service responsibilities and any service-level commitments are established for each engagement.
Cooma’s infrastructure offering includes rented bare-metal GPU capacity. Highlighted regions describe areas of focus, not facility ownership or live inventory. Facilities, quantities and availability are confirmed for each engagement.
Yes. Include your required location, processing and storage boundaries, access arrangements and timing in the initial discussion. The proposed deployment must be checked against those requirements before capacity is agreed.
Start a conversation
Tell us what you’re running, your preferred GPUs or node count, location, start date and duration. We’ll work through a configuration and capacity proposal with you.